A Cross-Scenario Survey and Analysis of Self-Evolving Multimodal Agents
Abstract
Recent work shows that multimodal agents increasingly self-improve without recurring human annotation. However, each self-improvement mechanism is designed and evaluated within a single scenario, leaving its preconditions unverified under cross-scenario transfer. This survey investigates the structural source of asymmetric mechanism transfer across four scenarios: multimodal reasoning, multimodal generation, GUI and Web navigation, and embodied manipulation.
We first formalize the self-evolving multimodal agent by four criteria and a differentia of self-reference, and adopt the three-stage self-evolving loop of experience generation, feedback acquisition, and update consolidation as our analytical framework to position the scenarios along ceilings on rollout count and feedback fidelity. Comparing self-evolving with fixed loops within each scenario separates the limitations that the scenario imposes from those inherent in the self-evolving design.
We then recast each mechanism as a trade-off that raises a scarce factor by presupposing a task-structural resource, such as output equivalence or checkable outcomes, and judge it portable, conditional, blocked, or redundant across scenarios. We attribute the asymmetry to divergent combinations of scarce factors and resources across opposite transfer directions, and identify the matched-budget measurements that could overturn these still untested verdicts.
Overview
How to read this survey
If you are new to the area
Start with the definition and the three-stage loop, then locate the four scenarios on the positioning matrix.
The portability table then shows, for each mechanism, which target scenarios hold the resource it presupposes.
If you are using the page as a reference
Jump directly to the library tables. The search bar matches method names, titles, venues, feedback signals, and backbones, and the filters separate scenarios as well as weight-updating from training-free loops.
The role tags in the feedback and update columns show whether the agent, a bootstrap artifact, or the environment realizes each meta-operator.
What counts as a self-evolving multimodal agent
The surveyed object is defined through a genus and a differentia. The genus comprises autonomous learning loops that satisfy four criteria, and the differentia, self-reference, requires the agent to realize at least one component of its own loop.
- DefinitionLoops in the genus that lack self-reference are fixed loops, for instance reinforcement learning against pre-collected answer keys under a stationary sampler.
- RoleThey serve as controls in every scenario, separating the constraints a scenario imposes from the intrinsic effects of self-evolution.
The three-stage self-evolving loop
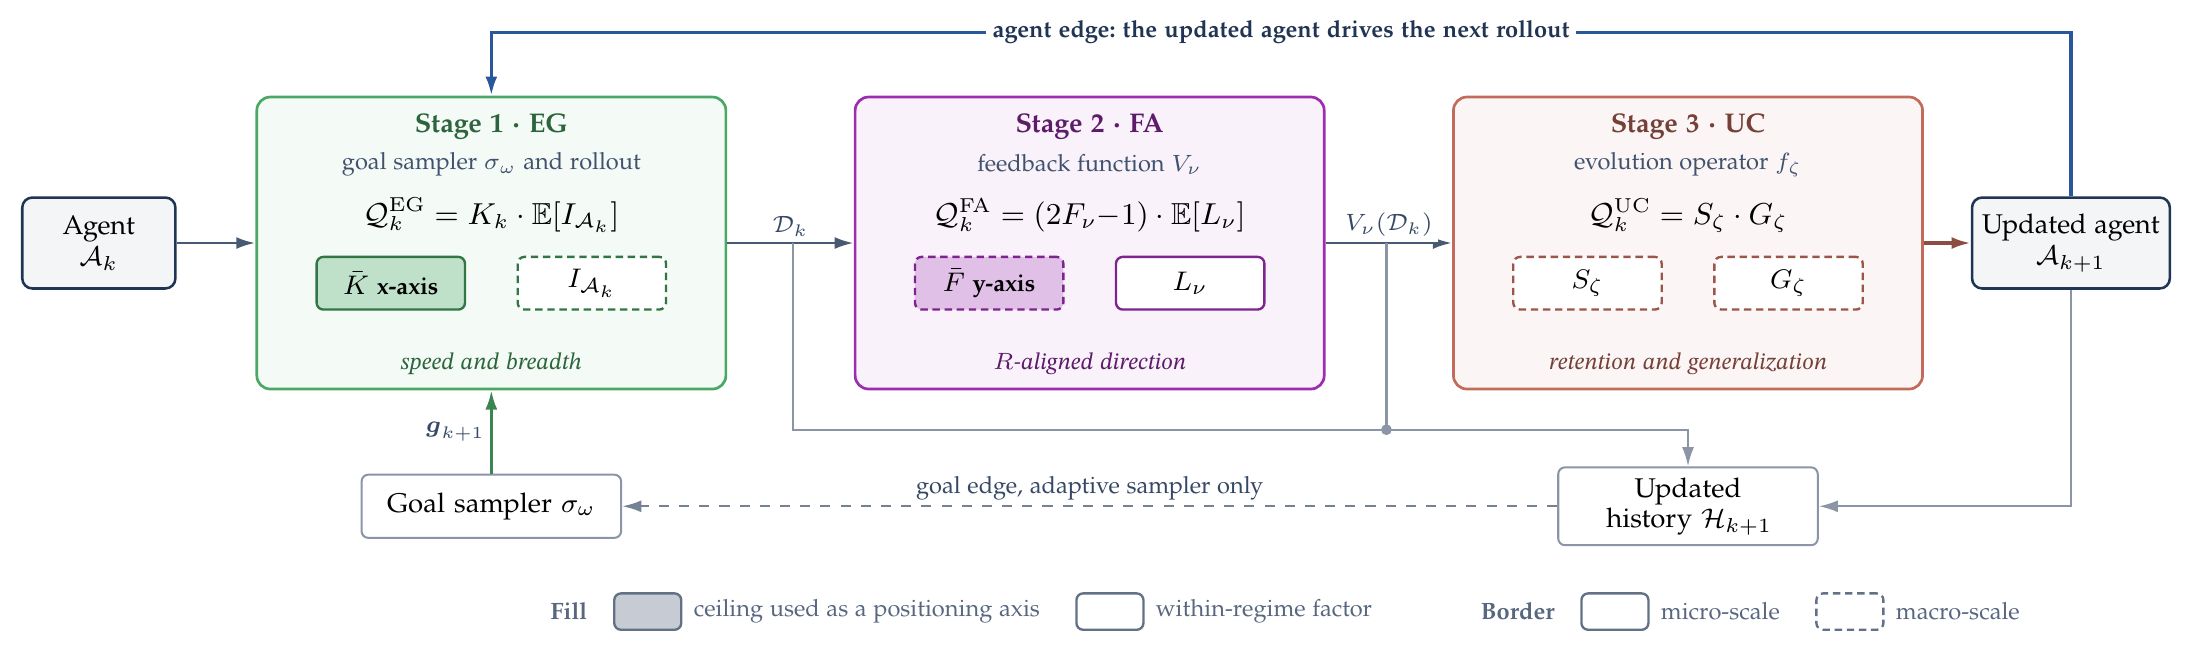
Each cycle decomposes into three stages, and each stage's bottleneck is formalized through two governing factors. The decomposition follows the generate, evaluate, and update pattern of Expert Iteration and ReST, and the analysis adds the factorization, the ceiling axes, and the cross-cycle edges.
Stage 1 · Experience Generation (EG)
Stage 2 · Feedback Acquisition (FA)
Stage 3 · Update Consolidation (UC)
Cross-scenario positioning matrix
Each scenario imposes ceilings on the rollouts affordable per cycle () and the feedback fidelity attainable by admissible evaluators (), which span a two-dimensional positioning matrix. Methods choose operating points below these ceilings, and the scenario fixes only the ceilings.
Cross-scenario asymmetry
Each self-evolving mechanism is a trade-off, in which the agent raises a scarce factor by replacing a fixed component with its own records, proposals, judgments, or memory writes, at the price of presupposing a task-structural resource, such as output equivalence or checkable outcomes. The asymmetry is attributed to the different combinations of scarce factors and resources that the two directions of a scenario pair encounter.
Portability of self-evolving mechanisms across target scenarios
| Mechanism | MR | MG | GW | EM |
|---|---|---|---|---|
| Presupposes a task-structural resource | ||||
| Success-conditioned allocation | portable* | conditional* | portable* | conditional*portable*e |
| Agent-posed goals | portable* | conditional* | portable*blockedg | conditionalblockedfportable*e |
| Record-conditioned goal generation | portable | conditional | portable*blockedg | conditionalblockedf |
| Program-checkable goal families | portable* | conditional* | portable | conditionalportable*e |
| Imagined rollouts in a world model | redundant | redundant | conditional | conditional* |
| Self-consistency vote | redundantaportable*b | conditional* | redundantcconditionaldblockedg | conditionalblockedf |
| Presupposes only the agent's model or a pre-loop artifact | ||||
| Self-judgment by the agent's model | redundantaportable*b | portable* | redundantcportable*dblockedg | portable*blockedf |
| Generator-confidence reward | redundantaportableb | portable* | redundantcportable | portable |
| Verifier refit on agent trajectories | redundantaportableb | portable* | portable*conditionalg | portableconditionalfportable*e |
| Frozen self-derived estimator | redundantaportable*b | portable* | portableconditionalg | portable*conditionalf |
| Episode reuse via memory, skills, or harnesses | portable* | portable* | portable*conditionalg | portable*conditionalf |
Trade-offs and degradation of self-evolving mechanisms11 mechanisms
(T) task-structural resource, (M) capability of the agent's model, and an artifact authored before the loop if unmarked. Evidence stops short of cross-round measurement for most degradation modes.
| Mechanism | Entry | Raises | Requires | Pays | Degradation |
|---|---|---|---|---|---|
| Experience generation | |||||
| Success-conditioned allocation | fixed task set with checkable outcomes (T) | coverage of tasks dropped by design | curriculum collapse | ||
| Agent-posed goals | checkable outcomes or output equivalence (T) | pooled keys or scripts, label accuracy 72% to 61% | curriculum collapse | ||
| Record-conditioned goal generation | checkable outcomes or output equivalence (T) | pooled keys or scripts | curriculum collapse | ||
| Program-checkable goal families | at a program-checked | program, simulator, or scripted scene checks (T) | coverage outside the family | forgetting | |
| Imagined rollouts in a world model | beyond via imagined rollouts | learnable short-horizon dynamics (T) | via model error, video degrades past 300 frames | distribution shift, model collapse | |
| Feedback acquisition | |||||
| Self-consistency vote | without keys | output equivalence (T), prior on the true answer (M) | rollouts per goal, label errors | compounding hacking | |
| Self-judgment by the agent's model | without checkers | generation-verification gap (M) | fidelity moving with the policy | compounding hacking | |
| Generator-confidence reward | without checkers | generator's confidence (M) | fidelity tied to updated weights | compounding hacking | |
| Verifier refit on agent trajectories | , or on free-form goals | labeled seed or reference set | fidelity moving with the policy | compounding hacking | |
| Frozen self-derived estimator | , or on free-form goals | demonstrations or calibration | fixed bias off the training support | distribution shift | |
| Update consolidation | |||||
| Episode reuse via memory or skills | , on hard goals | writer's generation-verification gap (M) or an online check (T) | exposure to the writer's errors | erroneous writes | |
Taxonomy
The four scenario chapters group methods by the meta-operator through which they answer the scenario's binding constraint, and the evaluation chapter adds benchmarks of self-evolving capability. Each item links directly into the corresponding part of the paper library.
Multimodal Reasoning 45 methods
Multimodal Generation 33 methods
GUI and Web Navigation 17 methods
Embodied Manipulation 26 methods
Self-Evolution Benchmarks 13 benchmarks
Paper library
The library has two parts. Curated papers follow the scenario taxonomies of the survey and record, for each self-evolving method, how feedback is acquired and how updates are consolidated. All papers list every reference cited in the survey under the chapter where it is first cited.
Curated papers
Self-evolving methods from the four scenario taxonomies and the self-evolution benchmarks of the evaluation chapter. Role tags mark which party realizes each meta-operator.
1. Multimodal Reasoning
Rollouts are single decoding passes and short answers admit exact match against a pre-collected or computed reference. Weight-updating loops mostly pose their own questions or train on unlabeled ones, which ties the evaluator to the model it trains, while training-free loops keep a frozen VLM and let the agent write the skills or tools it reuses.
1.1 Questions from datasets or fixed generators23 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | MM-UPTFirst SFT, Second RL, Third UPT: Continual Improving Multi-Modal LLM Reasoning via Unsupervised Post-Training | NeurIPS | A consensus, majority vote | B GRPO | Paper · Code |
| 2026 | TTRVTTRV: Test-Time Reinforcement Learning for Vision Language Models | CVPR | A consensus, answer frequency, entropy control | B GRPO | Paper · Code |
| 2026 | TTRSDTTRSD: Test-Time Reinforcement Learning with Self-Distillation for Vision-Language Models | arXiv | A consensus, agreement across three views | B token-selective GRPO | Paper · Code |
| 2026 | IQA-SelfEv.Self-Evolving Vision-Language Models for Image Quality Assessment via Voting and Ranking | ICLR | A consensus, pairwise majority vote | B GRPO | Paper · Code |
| 2026 | SelfJudgeWhen Models Judge Themselves: Unsupervised Self-Evolution for Multimodal Reasoning | arXiv | A consensus with self-judgmentf | B GRPO | Paper · Code |
| 2025 | SherlockSherlock: Self-Correcting Reasoning in Vision-Language Models | NeurIPS | A self-judgment, self-correction preference | B trajectory-level DPO | Paper · Code |
| 2025 | ISR-DPOISR-DPO: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective DPO | AAAI | A self-judgment, self-retrospective preference | B iterative DPO | Paper · Code |
| 2026 | BUSBUS: Brain-Inspired Unsupervised Self-Reflection via Backward Prediction for Multimodal Reasoning | arXiv | A self-judgment, backward prediction over sampled paths | B GRPO | Paper · Code |
| 2026 | Agent0-VLAgent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning | ICML | A self-judgment, tool-grounded self-critique | B joint GRPO | Paper · Code |
| 2026 | TVPtraining-freeTransductive Visual Programming: Evolving Tool Libraries from Experience for Spatial Reasoning | ICLR | A self-judgment, program quality score | B tool and example library (T+M) | Paper · Code |
| 2026 | Vision-ZeroVision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | ICLR | EA computed, game outcome | B self-play and RLVR | Paper · Code |
| 2026 | CwItraining-freeSelf-Evolving Code-with-Image Reasoning | arXiv | E computed, answer match | A validation-gated skill library (T+I) | Paper · Code |
| 2026 | Spatial Memory Ag.training-freeSpatial Memory Agent: Experience-Grounded Procedure Memory for Spatial Intelligence | arXiv | EB computed and key, environment reward | A memory cards (M) | Paper · Code |
| 2026 | EvoSpatialtraining-freeEvoSpatial: Experience-Driven Skill and Tool Evolution for Spatial Reasoning Agents | arXiv | EA computed checks and self-judgment | A skill and tool library (T+I) | Paper · Code |
| 2025 | Vision-SR1Self-Rewarding Vision-Language Model via Reasoning Decomposition | arXiv | BA key and self-judgment, perception re-answering | B multi-reward GRPO | Paper · Code |
| 2026 | M^2Notetraining-freeM^2Note: Continual Evolution of Vision Language Models via Mistake Notebook Learning | arXiv | BA key or self-judgment, rollback-gated | A mistake notebook (M) | Paper · Code |
| 2026 | VisualEvolvetraining-freeVisualEvolve: A Skill Self-Evolution Framework for Visual Reasoning | arXiv | B key, failure diagnosis | A validation-gated skill library (T+I) | Paper · Code |
| 2026 | CoWorldtraining-freeCoWorld Reasoner: Agentic Multimodal Reasoning with the Evolving Video World Model-Driven Harness | arXiv | B key, answer scoring | A selected harness (T+I) | Paper · Code |
| 2026 | Dynamotraining-freeDynamo: Dynamic Skill-Tool Evolution for Vision-Language Agents | arXiv | B key, training-sample accuracy | A gated skill-tool library (T+I) | Paper · Code |
| 2026 | PhysNotetraining-freePhysNote: Self-Knowledge Notes for Evolvable Physical Reasoning in Vision-Language Model | ICLRW | B key, answer match | A knowledge notes (M) | Paper · Code |
| 2026 | NeSy-Spatialtraining-freeSelf-Evolving Neuro-Symbolic Skills for Tool-Augmented Spatial Reasoning | arXiv | B key, revealed after answering | A skill library (T+I) | Paper · Code |
| 2026 | MetaForgeMetaForge: A Self-Evolving Multimodal Agent that Retrieves, Adapts, and Forges Tools On Demand | arXiv | B key, composite tool-use reward | A GRPO + tool library (T) | Paper · Code |
| 2025 | SyncLoopSyncLoop: A Multimodal Dual-Loop Framework for Self-Improving Mathematical Reasoning | arXiv | B key, constructed answers | B SFT and GRPO | Paper · Code |
1.2 Agent-generated questions17 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | EvoLMMEvoLMM: Self-Evolving Large Multimodal Models with Continuous Rewards | arXiv | A consensus, soft agreement | B REINFORCE | Paper · Code |
| 2026 | VisPlayVisPlay: Self-Evolving Vision-Language Models | CVPR | A consensus, majority vote | B GRPO | Paper · Code |
| 2026 | V-ZeroV-Zero: Self-Improving Multimodal Reasoning with Zero Annotation | arXiv | A consensus, majority vote | B iterative GRPO | Paper · Code |
| 2026 | iReasoneriReasoner: Trajectory-Aware Intrinsic Reasoning Supervision for Self-Evolving Large Multimodal Models | ACL Findings | A consensus, step-level agreement | B GRPO | Paper · Code |
| 2026 | Video-ZeroVideo-Zero: Self-Evolution Video Understanding | NeurIPS | A consensus, vote with temporal alignment | B alternating GRPO | Paper · Code |
| 2026 | EvoVidEvoVid: Temporal-Centric Self-Evolution for Video Large Language Models | arXiv | A consensus, vote with temporal IoU | B alternating GRPO | Paper · Code |
| 2026 | RISERISE: Reliable Improvement in Self-Evolving Vision-Language Models | arXiv | A consensus with supervisors | B alternating GRPO | Paper · Code |
| 2026 | VISEPaying More Attention to Visual Tokens in Self-Evolving Large Multimodal Models | arXiv | A consistency under image transformations | B REINFORCE | Paper · Code |
| 2026 | SVQSelf-Evolving Visual Questioner | arXiv | A self-judgmentf, rewrite and filter | B SFT | Paper · Code |
| 2026 | TrinityTrinity: Self-Evolving Vision-Language Models with a Self-Verifier | arXiv | A self-judgmentema, verifier scores | B joint GRPO | Paper · Code |
| 2026 | MarvoSelf-Evolving Visual Agent via Margin Reward | arXiv | A proposer answer, tool-use margin | B alternating GRPO | Paper · Code |
| 2026 | VideoEvoHarnesstraining-freeVideoEvoHarness: Self Evolving Agent Harness from Unlabeled Videos for Video Understanding | arXiv | A proposer answer from video memory | A validated harness (T+I) | Paper · Code |
| 2026 | VQSProgram-Verified Self-Evolution for Vision-Language Models | arXiv | EA computed, program answers | B GRPO | Paper · Code |
| 2026 | EVEEVE: Verifiable Self-Evolution of MLLMs via Executable Visual Transformations | arXiv | EA computed, code execution | B alternating GRPO | Paper · Code |
| 2026 | SpatialEvoSpatialEvo: Self-Evolving Spatial Intelligence via Deterministic Geometric Environments | arXiv | EA computed, geometric environment | B GRPO | Paper · Code |
| 2026 | DUELDUEL: Adversarial Self-Play for Multimodal Reasoning | arXiv | EA computed, claim-verification outcome | B GRPO | Paper · Code |
| 2026 | SAGESelf-Evolving Spatial Reasoning in Vision Language Models via Geometric Logic Consistency | arXiv | BE key and answer mapping, duality consistency | B GRPO | Paper · Code |
1.3 Agent-synthesized or retrieved images and videos5 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | MM-ZeroSelf-Evolving Vision Language Models for Structured Visual Understanding | EMNLP | A consensus, majority vote | B GRPO | Paper · Code |
| 2026 | Active-ZeroActive Zero: Self-Evolving Vision-Language Models through Active Environment Exploration | arXiv | A consensus, majority vote | B GRPO | Paper · Code |
| 2026 | ViCoVICO: Visual Environments Co-Evolving for Vision-Language Model Reasoning | NeurIPS | EB computed or key | B GRPO and RWR | Paper · Code |
| 2026 | Tempo-ZeroTempo-Zero: Recursive Self-Play in Executable Worlds for Video Reasoning | arXiv | EA computed, execution | B GRPO | Paper · Code |
| 2026 | PhysEvolvePhysEvolve: Verifier-Grounded Self-Evolution for Physical Reasoning with Executable Worlds | arXiv | EA computed, physics engine | B GRPO | Paper · Code |
2. Multimodal Generation
An open-ended image or video has no reference output outside sub-families such as object counts, rendered text, or program-drawn charts. Weight-updating loops mostly derive the verifier from the agent, letting its bias move with the policy, and training-free loops let a frozen backbone judge its own outputs and write its memory or skills.
2.1 Self-verifiers updated with the policy12 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | SOLACEImproving Text-to-Image Generation with Intrinsic Self-Confidence Rewards | CVPR | A denoising confidence under re-noising probes | B Flow-GRPO | Paper · Code |
| 2025 | IRISIRIS: Intrinsic Reward Image Synthesis | arXiv | A negative self-certainty over text and image tokens | B GRPO | Paper · Code |
| 2025 | CoRLCo-Reinforcement Learning for Unified Multimodal Understanding and Generation | NeurIPS | AB own token-embedding alignment, BLIP re-caption and LPIPS cycle consistency | B joint then task-specific GRPO | Paper · Code |
| 2025 | UniRLUniRL: Self-Improving Unified Multimodal Models via Supervised and Reinforcement Learning | arXiv | A own answers against answers fixed at prompt construction | B SFT and GRPO | Paper · Code |
| 2025 | SUDERSUDER: Self-Improving Unified Large Multimodal Models for Understanding and Generation with Dual Self-Rewards | arXiv | A reverse-direction likelihood in both branches | B SimPO or GRPO | Paper · Code |
| 2025 | SILMMSILMM: Self-Improving Large Multimodal Models for Compositional Text-to-Image Generation | CVPR | A own answers to self-decomposed questions | B DPO or KC-DPO | Paper · Code |
| 2026 | InternalGapTurning Internal Gap into Self-Improvement: Promoting the Generation-Understanding Unification in MLLMs | ICLR | A own yes/no probability of alignment | B SFT and DPO | Paper · Code |
| 2026 | Read It BackRead It Back: Pretrained MLLMs Are Zero-Shot Reward Models for Text-to-Image Generation | NeurIPS | A own likelihood of the prompt given the image | B AWM online RL | Paper · Code |
| 2026 | GvULearning to Generate via Understanding: Understanding-Driven Intrinsic Rewarding for Unified Multimodal Models | arXiv | A own token-level likelihood of the prompt | B GRPO | Paper · Code |
| 2026 | ASGAsk, Solve, Generate: Self-Evolving Unified Multimodal Understanding and Generation via Self-Consistency Rewards | arXiv | A answer agreement across seven framings, cycle captioning | B GRPO on three LoRA adapters | Paper · Code |
| 2026 | Safe CodebooksSafe Autoregressive Image Generation with Iterative Self-Improving Codebooks | ICML | A own judgment of unsafe content | B codebook projection, null-space fine-tuning | Paper · Code |
| 2026 | JarvisEvoJarvisEvo: Towards a Self-Evolving Photo Editing Agent with Synergistic Editor-Evaluator Optimization | CVPR | A own evaluator, aligned to human scores fixed before the loop | B SEPO RL and reflection fine-tuning | Paper · Code |
2.2 Co-evolving or lagged verifiers5 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | SRL-VLMSelf-Rewarding Large Vision-Language Models for Optimizing Prompts in Text-to-Image Generation | ACL Findings | A previous-iteration LVLMp, aesthetics and alignment | B DPO | Paper · Code |
| 2026 | Image as Its Own RewardThe Image as Its Own Reward: Reinforcement Learning with Adversarial Reward for Image Generation | CVPR | A PickScore or DINO modelc, Qwen-Image positives | B GRPO | Paper · Code |
| 2026 | Dual-IPODual-IPO: Dual-Iterative Preference Optimization for Text-to-Video Generation | ICLR | A criticc refined on its pseudo-labels and a human seed set | B Diffusion-DPO or KTO | Paper · Code |
| 2026 | ImageRSItraining-freeImageRSI: Verification-Driven Recursive Self-Improvement for Agentic Image Generation | arXiv | A judge retrained on loop records, blinded A/B admission | A experience library (I), judge SFT and GRPO | Paper · Code |
| 2026 | UniEvo-VLUniEvo-VL: An On-policy Self-Distillation Training Recipe for Multimodal Model Self-improvement | arXiv | AB moving-average teacherema with external critiques | B on-policy self-distillation | Paper · Code |
2.3 Frozen self-verifiers11 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | PRISMPRISM: Prompt Refinement via Image-Grounded Self-Rewarding Mechanism for Text-to-Image Generation | arXiv | A initial VLMf, dimension scores | B GSPO | Paper · Code |
| 2026 | MT-OPSDOn-Policy Self-Distillation for Multi-Turn Image Editing | arXiv | A clean-conditioned checkpointf, gated promotion | B on-policy self-distillation | Paper · Code |
| 2026 | ManimAgenttraining-freeManimAgent: Self-Evolving Multimodal Agents for Visual Education | arXiv | EA renderer errors, keyframe reviews | A gated success and failure memory (M) | Paper · Code |
| 2026 | COMFYCLAWtraining-freeCOMFYCLAW: Self-Evolving Skill Harnesses for Image Generation Workflows | arXiv | A region checklists, held-out gain gate | A skill library (T) | Paper · Code |
| 2024 | SceneCrafttraining-freeSceneCraft: An LLM Agent for Synthesizing 3D Scenes as Blender Code | ICML | A review of renderss against parsed constraints | A constraint-function library (T) | Paper · Code |
| 2026 | EvoDesigntraining-freeEvoDesign: Agentic Editable Diagram Creation via Design Expertise Evolution | arXiv | A refiner critiques of each render | A three-tier design memory (M+I) | Paper · Code |
| 2026 | SymbOmnitraining-freeSymbOmni: Evolving Agentic Omni Models via Symbolic Concept Learning | arXiv | EA compiler errors, evaluation agents | A symbolic concept memory (T+I) | Paper · Code |
| 2026 | SIDiffAgenttraining-freeSIDiffAgent: Self-Improving Diffusion Agent | arXiv | A evaluation agents, aesthetics and alignment | A trajectory memory (M) | Paper · Code |
| 2026 | Drawing Middlewaretraining-freeAutomatic Method Illustration Generation for AI Scientific Papers via Drawing Middleware Creation, Evolution, and Orchestration | arXiv | AB evaluator agents, reference illustrations | A middleware library with rollback (T) | Paper · Code |
| 2026 | MemoGentraining-freeMemoGen: Can Past Experience Improve Future Text-to-Image Generation? | arXiv | AB controller self-review, independent memory judge | A experience memory (M) | Paper · Code |
| 2026 | PhysRepairtraining-freeAgentic Physics-Grounded Video Generation via Memory-Augmented In-Context Reasoning | arXiv | EA re-diagnosiss with perception tools | A repair experience memory (M) | Paper · Code |
2.4 External or programmatic verifiers5 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | RSI in UMMsRecursive Self-Improvement in Unified Multimodal Models | arXiv | E execution of own programs against the specification | B fine-tuning of generation, understanding, programs | Paper · Code |
| 2026 | MATEMutually Adversarial Self-Training with Evolving Data for Unified Multimodal Models | arXiv | B frozen UnifiedReward scorer, SigLIP source consistency | B GRPO on both branches | Paper · Code |
| 2026 | RSIgenRSIgen: Reciprocal Self-Improvement for Agentic Visual Generation | arXiv | B fixed external evaluator | B agent and generator updates | Paper · Code |
| 2026 | OctoT2IOctoT2I: A Self-Evolving Agentic Text-to-Image Router | CVPR | B frozen MLLM probability of alignment | A routing knowledge base (I) | Paper · Code |
| 2026 | GenEvolveGenEvolve: Self-Evolving Image Generation Agents via Tool-Orchestrated Visual Experience Distillation | arXiv | B Gemini KScore judge, program-sufficiency judge | A GRPO, self-distillation from own experience-conditioned targets | Paper · Code |
3. GUI and Web Navigation
Each rollout is a multi-step episode that pays environment latency at every step, whereas the inspectable end state of an application or a web page keeps the attainable fidelity high in sandboxed environments. Weight-updating loops allocate scarce rollouts by proposing or reweighting goals, and training-free loops reuse each episode through memory or skills.
3.1 Stationary sampling of fixed goals10 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | Mobile-Agent-Etraining-freeMobile-Agent-E: Self-Evolving Mobile Assistant for Complex Tasks | arXiv | A Experience Reflectors over action and error historiess | A Tips and Shortcuts (M, T) | Paper · Code |
| 2025 | Agent Straining-freeAgent S: An Open Agentic Framework that Uses Computers Like a Human | ICLR | A self-evaluator summaries of each task | A narrative and episodic memory (M) | Paper · Code |
| 2025 | MobileStewardtraining-freeMobileSteward: Integrating Multiple App-Oriented Agents with Self-Evolution to Automate Cross-App Instructions | KDD | A StewardAgent evaluations | A expertise and guideline memory (M) | Paper · Code |
| 2025 | AppAgentXtraining-freeAppAgentX: Evolving GUI Agents as Proficient Smartphone Users | arXiv | B benchmark success evaluation | A shortcut graph (M, T) | Paper · Code |
| 2026 | WebCoachtraining-freeWebCoach: Self-Evolving Web Agents with Cross-Session Memory Guidance | ICLR | A actor self-evaluation, condensed by Qwen3-8B | B cross-session episodic memory (M) | Paper · Code |
| 2026 | EvoSkill-GUItraining-freeReflect, Revise, Reuse: Training-Free Skill Evolution for GUI Agents | arXiv | AB isolated same-backbone critic, terminal task reward | A skill packages (M, T) | Paper · Code |
| 2026 | MAGNETtraining-freeMAGNET: Towards Adaptive GUI Agents with Memory-Driven Knowledge Evolution | arXiv | B AndroidWorld success scripts | A procedural and grounding memory (M) | Paper · Code |
| 2024 | DigiRLDigiRL: Training In-the-Wild Device-Control Agents with Autonomous Reinforcement Learning | NeurIPS | AB VLM evaluator with 2.8% error, value functions filtering stepsc | B offline-to-online RL with replay | Paper · Code |
| 2026 | MagicGUI-RMSMagicGUI-RMS: A Multi-Agent Reward Model System for Self-Evolving GUI Agents via Automated Feedback Reflux | arXiv | AB domain reward model on the agent backbonec, GPT-4o arbitration | B SFT of agent and reward model | Paper · Code |
| 2026 | Agent S4training-freeAgent S4: Evolutionary Computer Use | OpenReview | B OSWorld V2 validation evaluators select parents | A evolved interfaces and usage knowledge (T, I) | Paper · Code |
3.2 Adaptive sampling of fixed goals3 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | DART-GUIEfficient Multi-Turn RL for GUI Agents via Decoupled Training and Adaptive Data Curation | arXiv | B OSWorld evaluation scripts | B decoupled multi-turn RL | Paper · Code |
| 2026 | MobileRLMobileRL: Online Agentic Reinforcement Learning for Mobile GUI Agents | ICLR | B rule-based AndroidWorld rewards, fine-tuned VLM for AndroidLab | B AdaGRPO with positive replay | Paper · Code |
| 2025 | UI-GenieUI-Genie: A Self-Improving Approach for Iteratively Boosting MLLM-Based Mobile GUI Agents | NeurIPS | A reward model fit on continuation-rollout step labelsc | B SFT of agent and reward model | Paper · Code |
3.3 Adaptive generation of new goals4 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | SEAgentSEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience | ICML | B World State Model trained on GPT-4o judgments, step-level | B GRPO and adversarial imitation | Paper · Code |
| 2026 | ACuRLAutonomous Continual Learning for Environment Adaptation of Computer-Use Agents | arXiv | B CUAJudge outcome judgment from key screenshots | B RL | Paper · Code |
| 2026 | SCALELearning to Adapt: Self-Improving Web Agent via Cognitive-Aware Exploration | CVPR | A predicted against observed next screens | B fine-tuning of Selector and Predictor | Paper · Code |
| 2025 | SkillWeavertraining-freeSkillWeaver: Web Agents can Self-Improve by Discovering and Honing Skills | arXiv | A success check from trajectory and final screenshots | A executable API library (T) | Paper · Code |
4. Embodied Manipulation
Each rollout costs robot time, a reset, and wear, and each outcome is checkable only by a per-task classifier or a learned judge. Simulation relaxes both ceilings, and the methods differ chiefly in feedback source, namely simulator predicates, agent-derived verifiers, or external judges.
4.1 Environment feedback11 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | EmbodiedRSItraining-freeEmbodiedRSI: Active Continual Robot Learning through Hypothesis-Guided Co-Evolution | arXiv | E physical trial outcomes | A code, skills, hierarchical memory (T, M), PPO memory policy | Paper · Code |
| 2026 | RoboBridgetraining-freeRoboBridge: A Self-Evolving Embodied Agent Framework for Sim-to-Real Transfer | arXiv | EB completion predicate, held-out validation gate | A versioned skill documents (M, I) | Paper · Code |
| 2026 | EmbodiedEvotraining-freeEmbodiedEvo: Self-Evolving Coding Agent for Physical Intelligence | arXiv | E completion, errors, termination status | A executable skills, lessons (T, M) | Paper · Code |
| 2026 | RoboHarn-Evotraining-freeRoboHarn-Evo: Evolving Hierarchical Physical Knowledge for Self-Improving Robotic Manipulation | arXiv | E physical feedback on rollouts | A hierarchical physical knowledge (M) | Paper · Code |
| 2026 | BATONtraining-freeDon't Drop the BATON: Long-Horizon Robot Manipulation via Agentic Subtask Exploration and Transition-Aware Memory | arXiv | E subtask outcomes, entry-state checks | A verified subtask units (M) | Paper · Code |
| 2026 | Harness VLAtraining-freeHarness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents | arXiv | E primitive post-conditions, task success | A global memory of verified sequences (M) | Paper · Code |
| 2026 | ASPIREtraining-freeASPIRE: Agentic Skills Discovery for Robotics | arXiv | E execution and collision feedback | A growing skill library (T) | Paper · Code |
| 2026 | ViSkillViSkill: Reinforcing VLM Agents with Evolving Visual-Native Skills | arXiv | AE binary success, skill-guided partial credit | A PPO with skill cards (M) | Paper · Code |
| 2026 | Policy-Level RSIPolicy-Level Recursive Self-Improvement for Embodied AI with a Criticality World Model | arXiv | E simulator failure labels | B PPO with BC anchor, risk-gated specialist | Paper · Code |
| 2026 | MERLTrust-Calibrated VLA Policy Post-Training with Evolving Imagination | arXiv | EA terminal success, reward proxy refit on rolloutsc | B RL on real and imagined chunks | Paper · Code |
| 2026 | Scale and Selectiontraining-freeScale and Selection: What Makes Automatic Harness Evolution Work for Visual-Interface Robot Agents | arXiv | E built-in success detectors, champion-challenger acceptance | A harness prompts, tools, control rules (I, T) | Paper · Code |
4.2 Agent-generated feedback10 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2026 | SC-VLAtraining-freeSelf-Correcting VLA: Online Action Refinement via Sparse World Imagination | arXiv | A predicted progress and displacementf | B SAC residual policy | Paper · Code |
| 2025 | Self-Improving EFMsSelf-Improving Embodied Foundation Models | NeurIPS | A decrease in predicted steps-to-gof | B REINFORCE | Paper · Code |
| 2026 | RoboEvolveRoboEvolve: Co-Evolving Planner-Simulator for Robotic Manipulation with Limited Data | arXiv | A planner as zero-shot criticc | B GRPO and DPO for planner and simulator | Paper · Code |
| 2026 | Motus2Motus2: A Self-Evolving General World Model for Dexterous Manipulation | arXiv | A own value model on imagined futuresf | B DiffusionNFT on action parameters | Paper · Code |
| 2026 | EEAgenttraining-freeEvolvable Embodied Agent for Robotic Manipulation via Long Short-Term Reflection and Optimization | arXiv | AE binary success, failure localizations | A long- and short-term reflections (M, I) | Paper · Code |
| 2026 | SHAPERtraining-freeSelf-Evolving Embodied Agents via Skill-Harness Evolution | arXiv | AE binary success, round-level critiques | A skill text, context code (I, T) | Paper · Code |
| 2026 | SEARtraining-freeSEAR: Self-Evolving Agentic Robotics | arXiv | AB own local checks, judge on validation seeds | A code skills, written memories (T, M) | Paper · Code |
| 2025 | PragmaBottraining-freeA Pragmatist Robot: Learning to Plan Tasks by Experiencing the Real World | arXiv | A VLM success detectors | A reflections in long-term memory (M) | Paper · Code |
| 2026 | RATstraining-freePlayful Agentic Robot Learning | arXiv | AE goal and per-step verifierss, deterministic checks | A code skill library (T) | Paper · Code |
| 2026 | RoboRSItraining-freeRoboRSI: Stable, Efficient, and Reusable Robot Self-Evolution in Complex Real-World Environments | arXiv | AE reviewer postcondition checkss, simulator success gate | A skill hierarchy, guidance (T, M) | Paper · Code |
4.3 External-model feedback5 methods
| Year | Method | Venue | Feedback () | Update () | Links |
|---|---|---|---|---|---|
| 2025 | Reflection-VLAReflection-Based Task Adaptation for Self-Improving VLA | arXiv | BE GPT-4o-composed dense reward, binary success | B PPO and SFT on own successes | Paper · Code |
| 2026 | EvoVLAEvoVLA: Self-Evolving Vision-Language-Action Model | ECCV | BA Gemini stage dictionary scored by CLIP, pose curiosity | B PPO with dual critics | Paper · Code |
| 2026 | Find Somethingtraining-freeFind Something You Can't Do: Agentic Real-World Reinforcement Learning for Self-Improving VLA Models | arXiv | B VLM success from pre- and post-images | B residual off-policy RL | Paper · Code |
| 2026 | Agentic-VLAAgentic-VLA: Efficient Online Adaptation for Vision-Language-Action Models | ICML | BA VLAC progress, sub-goal weights by success | B GRPO, memory of adapted weights (M) | Paper · Code |
| 2026 | Robo-COPCo-Evolving Robot Orchestrators and Policies through Deployment | arXiv | B text and video judges, windowed verification | A LoRA adapters, skills, task memory (M, T) | Paper · Code |
5. Self-Evolution Benchmarks
Benchmarks that let an agent write to persistent components across rounds or tasks and report how its score changes, grouped by scenario. They are the measurement side of the survey and record which of the loop-level quantities each benchmark reports.
5.2 Embodied manipulation3 entries
| Year | Benchmark | Tasks | Feedback | Writes | Links |
|---|---|---|---|---|---|
| 2026 | PhysRSI-evalWhere is Physical RSI Capability From? An Observational Scaling Law of LLM-as-Policy | 18 tasks, RoboDojo | RoboDojo score B† | M, T | Paper · Code |
| 2026 | RobotAgentBenchRobotAgentBench: Towards Open-World Robot Autonomy | 116 tasks, Isaac Sim | execution feedback | T | Paper · Code |
| 2026 | SEARSEAR: Self-Evolving Agentic Robotics | 330 simulated, 5 hardware tasks | sealed judge B† | P, M, T | Paper · Code |
5.3 Across reasoning, generation, and manipulation1 entries
5.4 Outside the four scenarios7 entries
| Year | Benchmark | Tasks | Feedback | Writes | Links |
|---|---|---|---|---|---|
| 2026 | PokeGymMastering PokeGym: Graph-Guided Multimodal Evolution at Test Time | 114 tasks, Pokémon Z-A | composite score B+E† | any (T, I) | Paper · Code |
| 2026 | GameVerse*GameVerse: Can Vision-Language Models Learn from Video-Based Reflection? | 15 games | failure video E | I | Paper · Code |
| 2026 | OmniGameArenaOmniGameArena: A Unified UE5 Benchmark for VLM Game Agents with Improvement Dynamics | 2 of 12 UE5 games | progress score B† | M, I | Paper · Code |
| 2026 | SelfImprove-BenchSelfImprove-Bench: Evaluating Generalization in Self-Improving Agents | 6 games | score, success E† | any (M, T, I) | Paper · Code |
| 2026 | EmbodiedCLBenchEmbodiedCLBench: Evaluating Continual Learning for Self-Evolving Embodied Agents | 268 tasks, offline state graphs | unstated | M, T | Paper · Code |
| 2026 | GameBoyWorldsGameBoyWorlds: A Testbed for Self-Improvement in Embodied Video Games | 500 tasks, 10 games | intrinsic or self-judged A | any (P, M, I) | Paper · Code |
| 2026 | MC-EvoBenchMC-EvoBench: Auditing Experience-Driven Self-Improvement in Minecraft Agents | 80 tasks, Minecraft | stage verifiers B† | M | Paper · Code |
All papers
Every reference cited in the survey, listed under the chapter where it is first cited and ordered by year.
1. Introduction42 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2024 | Agent AI: Surveying the Horizons of Multimodal Interaction | arXiv | Paper · Code |
| 2024 | Large Multimodal Agents: A Survey | arXiv | Paper · Code |
| 2024 | DigiRL: Training In-the-Wild Device-Control Agents with Autonomous Reinforcement Learning | NeurIPS | Paper · Code |
| 2024 | A Survey on Large Language Model Based Autonomous Agents | Front. Comput. Sci. | Paper · Code |
| 2025 | A Survey on Agentic Multimodal Large Language Models | arXiv | Paper · Code |
| 2025 | SUDER: Self-Improving Unified Large Multimodal Models for Understanding and Generation with Dual Self-Rewards | arXiv | Paper · Code |
| 2025 | SILMM: Self-Improving Large Multimodal Models for Compositional Text-to-Image Generation | CVPR | Paper · Code |
| 2025 | Co-Reinforcement Learning for Unified Multimodal Understanding and Generation | NeurIPS | Paper · Code |
| 2025 | EvoVLA: Self-Evolving Vision-Language-Action Model | arXiv | Paper · Code |
| 2025 | Self-Improving Embodied Foundation Models | NeurIPS | Paper · Code |
| 2025 | EvoLMM: Self-Evolving Large Multimodal Models with Continuous Rewards | arXiv | Paper · Code |
| 2025 | First SFT, Second RL, Third UPT: Continual Improving Multi-Modal LLM Reasoning via Unsupervised Post-Training | NeurIPS | Paper · Code |
| 2025 | OS Agents: A Survey on MLLM-based Agents for General Computing Devices Use | ACL | Paper · Code |
| 2025 | A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems | arXiv | Paper · Code |
| 2025 | Adaptation of Agentic AI: A Survey of Post-Training, Memory, and Skills | arXiv | Paper · Code |
| 2025 | Self-Improvement in Multimodal Large Language Models: A Survey | EMNLP Findings | Paper · Code |
| 2025 | The Rise and Potential of Large Language Model Based Agents: A Survey | Sci. China Inf. Sci. | Paper · Code |
| 2026 | GUI Agents with Reinforcement Learning: Toward Digital Inhabitants | arXiv | Paper · Code |
| 2026 | VisPlay: Self-Evolving Vision-Language Models | CVPR | Paper · Code |
| 2026 | Self-Evolving Vision Language Models for Structured Visual Understanding | EMNLP | Paper · Code |
| 2026 | V-Zero: Self-Improving Multimodal Reasoning with Zero Annotation | arXiv | Paper · Code |
| 2026 | Active Zero: Self-Evolving Vision-Language Models through Active Environment Exploration | arXiv | Paper · Code |
| 2026 | Improving Text-to-Image Generation with Intrinsic Self-Confidence Rewards | CVPR | Paper · Code |
| 2026 | Turning Internal Gap into Self-Improvement: Promoting the Generation-Understanding Unification in MLLMs | ICLR | Paper · Code |
| 2026 | Autonomous Continual Learning for Environment Adaptation of Computer-Use Agents | arXiv | Paper · Code |
| 2026 | SEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience | ICML | Paper · Code |
| 2026 | MobileRL: Online Agentic Reinforcement Learning for Mobile GUI Agents | ICLR | Paper · Code |
| 2026 | SEAR: Self-Evolving Agentic Robotics | arXiv | Paper · Code |
| 2026 | Find Something You Can't Do: Agentic Real-World Reinforcement Learning for Self-Improving VLA Models | arXiv | Paper · Code |
| 2026 | World-VLA-Loop: Closed-Loop Learning of Video World Model and VLA Policy | arXiv | Paper · Code |
| 2026 | Trust-Calibrated VLA Policy Post-Training with Evolving Imagination | arXiv | Paper · Code |
| 2026 | Agentic Visual Generation: From Generative Models to Agentic Control | arXiv | Paper · Code |
| 2026 | Recursive Self-Improvement in AI: From Bounded Self-Refinement to Autonomous Research Loops | arXiv | Paper · Code |
| 2026 | A Survey of Self-Evolving Agents: What, When, How, and Where to Evolve on the Path to Artificial Super Intelligence | TMLR | Paper · Code |
| 2026 | Trustworthy Recursive Self-Improvement in the Era of Large Models: Foundation, Risks, Evaluation and Open Challenges | arXiv | Paper · Code |
| 2026 | Self-Improvements in Modern Agentic Systems: A Survey | arXiv | Paper · Code |
| 2026 | A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution | TechRxiv | Paper · Code |
| 2026 | Self-Evolving Agents as Dynamic Graph Transformation: A Survey and New Perspective | arXiv | Paper · Code |
| 2026 | The Landscape of Agentic Reinforcement Learning for LLMs: A Survey | TMLR | Paper · Code |
| 2026 | Self-Evolving Embodied AI | arXiv | Paper · Code |
| 2026 | Seeing, Maintaining, and Learning: The Evolution of Multimodal Agent Memory | arXiv | Paper · Code |
| 2026 | Ask, Solve, Generate: Self-Evolving Unified Multimodal Understanding and Generation via Self-Consistency Rewards | arXiv | Paper · Code |
2. Preliminaries82 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 1998 | Planning and Acting in Partially Observable Stochastic Domains | Artificial Intelligence | Paper · Code |
| 2009 | Artificial Intelligence: A Modern Approach | Prentice Hall | Paper · Code |
| 2011 | A Reduction of Imitation Learning and Structured Prediction to No-Regret Online Learning | AISTATS | Paper · Code |
| 2015 | Universal Value Function Approximators | ICML | Paper · Code |
| 2017 | Overcoming Catastrophic Forgetting in Neural Networks | PNAS | Paper · Code |
| 2017 | Gradient Episodic Memory for Continual Learning | NeurIPS | Paper · Code |
| 2017 | Thinking Fast and Slow with Deep Learning and Tree Search | NeurIPS | Paper · Code |
| 2018 | Intrinsic Motivation and Automatic Curricula via Asymmetric Self-Play | ICLR | Paper · Code |
| 2018 | A General Reinforcement Learning Algorithm That Masters Chess, Shogi, and Go through Self-Play | Science | Paper · Code |
| 2019 | Paired Open-Ended Trailblazer (POET): Endlessly Generating Increasingly Complex and Diverse Learning Environments and Their Solutions | arXiv | Paper · Code |
| 2020 | Self-Training with Noisy Student Improves ImageNet Classification | CVPR | Paper · Code |
| 2020 | FixMatch: Simplifying Semi-Supervised Learning with Consistency and Confidence | NeurIPS | Paper · Code |
| 2020 | Test-Time Training with Self-Supervision for Generalization under Distribution Shifts | ICML | Paper · Code |
| 2020 | Automatic Curriculum Learning for Deep RL: A Short Survey | IJCAI | Paper · Code |
| 2020 | Emergent Complexity and Zero-Shot Transfer via Unsupervised Environment Design | NeurIPS | Paper · Code |
| 2021 | Meta Pseudo Labels | CVPR | Paper · Code |
| 2021 | Tent: Fully Test-Time Adaptation by Entropy Minimization | ICLR | Paper · Code |
| 2021 | Prioritized Level Replay | ICML | Paper · Code |
| 2021 | Learning with AMIGo: Adversarially Motivated Intrinsic Goals | ICLR | Paper · Code |
| 2022 | Autonomous Reinforcement Learning: Formalism and Benchmarking | ICLR | Paper · Code |
| 2022 | MEMO: Test Time Robustness via Adaptation and Augmentation | NeurIPS | Paper · Code |
| 2022 | Continual Test-Time Domain Adaptation | CVPR | Paper · Code |
| 2022 | Efficient Test-Time Model Adaptation without Forgetting | ICML | Paper · Code |
| 2022 | STaR: Bootstrapping Reasoning with Reasoning | NeurIPS | Paper · Code |
| 2022 | Training Language Models to Follow Instructions with Human Feedback | NeurIPS | Paper · Code |
| 2022 | Training a Helpful and Harmless Assistant with Reinforcement Learning from Human Feedback | arXiv | Paper · Code |
| 2022 | Evolving Curricula with Regret-Based Environment Design | ICML | Paper · Code |
| 2023 | RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control | CoRL | Paper · Code |
| 2023 | Efficient Guided Generation for Large Language Models | arXiv | Paper · Code |
| 2023 | Grammar-Constrained Decoding for Structured NLP Tasks without Finetuning | EMNLP | Paper · Code |
| 2023 | MemGPT: Towards LLMs as Operating Systems | arXiv | Paper · Code |
| 2023 | ReAct: Synergizing Reasoning and Acting in Language Models | ICLR | Paper · Code |
| 2023 | Toolformer: Language Models Can Teach Themselves to Use Tools | NeurIPS | Paper · Code |
| 2023 | Self-Consistency Improves Chain of Thought Reasoning in Language Models | ICLR | Paper · Code |
| 2023 | Self-Refine: Iterative Refinement with Self-Feedback | NeurIPS | Paper · Code |
| 2023 | Self-Instruct: Aligning Language Models with Self-Generated Instructions | ACL | Paper · Code |
| 2023 | Reinforced Self-Training (ReST) for Language Modeling | arXiv | Paper · Code |
| 2023 | Llama 2: Open Foundation and Fine-Tuned Chat Models | arXiv | Paper · Code |
| 2023 | Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation | arXiv | Paper · Code |
| 2023 | Reflexion: Language Agents with Verbal Reinforcement Learning | NeurIPS | Paper · Code |
| 2024 | InternVL: Scaling Up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks | CVPR | Paper · Code |
| 2024 | Chameleon: Mixed-Modal Early-Fusion Foundation Models | arXiv | Paper · Code |
| 2024 | Show-o: One Single Transformer to Unify Multimodal Understanding and Generation | arXiv | Paper · Code |
| 2024 | Emu3: Next-Token Prediction Is All You Need | arXiv | Paper · Code |
| 2024 | XGrammar: Flexible and Efficient Structured Generation Engine for Large Language Models | arXiv | Paper · Code |
| 2024 | ToolLLM: Facilitating Large Language Models to Master 16000+ Real-World APIs | ICLR | Paper · Code |
| 2024 | Gorilla: Large Language Model Connected with Massive APIs | NeurIPS | Paper · Code |
| 2024 | RoboGen: Towards Unleashing Infinite Data for Automated Robot Learning via Generative Simulation | ICML | Paper · Code |
| 2024 | DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models | arXiv | Paper · Code |
| 2024 | ExpeL: LLM Agents Are Experiential Learners | AAAI | Paper · Code |
| 2024 | Voyager: An Open-Ended Embodied Agent with Large Language Models | TMLR | Paper · Code |
| 2024 | CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing | ICLR | Paper · Code |
| 2024 | Teaching Large Language Models to Self-Debug | ICLR | Paper · Code |
| 2024 | Chain-of-Verification Reduces Hallucination in Large Language Models | ACL Findings | Paper · Code |
| 2024 | Beyond Human Data: Scaling Self-Training for Problem-Solving with Language Models | TMLR | Paper · Code |
| 2024 | Tulu 3: Pushing Frontiers in Open Language Model Post-Training | arXiv | Paper · Code |
| 2024 | TextGrad: Automatic ``Differentiation'' via Text | arXiv | Paper · Code |
| 2024 | Self-Rewarding Language Models | ICML | Paper · Code |
| 2024 | Promptbreeder: Self-Referential Self-Improvement via Prompt Evolution | ICML | Paper · Code |
| 2024 | LLM Evaluators Recognize and Favor Their Own Generations | NeurIPS | Paper · Code |
| 2025 | Qwen2.5-VL Technical Report | arXiv | Paper · Code |
| 2025 | Qwen3-VL Technical Report | arXiv | Paper · Code |
| 2025 | Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling | arXiv | Paper · Code |
| 2025 | Scaling LLM Test-Time Compute Optimally Can Be More Effective than Scaling Parameters for Reasoning | ICLR | Paper · Code |
| 2025 | Corvid: Improving Multimodal Large Language Models Towards Chain-of-Thought Reasoning | ICCV | Paper · Code |
| 2025 | *_0.6: a VLA That Learns From Experience | arXiv | Paper · Code |
| 2025 | Kimi k1.5: Scaling Reinforcement Learning with LLMs | arXiv | Paper · Code |
| 2025 | ZeroGUI: Automating Online GUI Learning at Zero Human Cost | arXiv | Paper · Code |
| 2025 | Absolute Zero: Reinforced Self-Play Reasoning with Zero Data | NeurIPS | Paper · Code |
| 2025 | TTRL: Test-Time Reinforcement Learning | NeurIPS | Paper · Code |
| 2025 | Godel Agent: A Self-Referential Agent Framework for Recursively Self-Improvement | ACL | Paper · Code |
| 2025 | Position: Truly Self-Improving Agents Require Intrinsic Metacognitive Learning | ICML | Paper · Code |
| 2025 | Efficient Multi-Turn RL for GUI Agents via Decoupled Training and Adaptive Data Curation | arXiv | Paper · Code |
| 2026 | SimpleVLA-RL: Scaling VLA Training via Reinforcement Learning | ICLR | Paper · Code |
| 2026 | Program-Verified Self-Evolution for Vision-Language Models | arXiv | Paper · Code |
| 2026 | Co-Evolving LLM Decision and Skill Bank Agents for Long-Horizon Tasks | arXiv | Paper · Code |
| 2026 | Agentic-VLA: Efficient Online Adaptation for Vision-Language-Action Models | ICML | Paper · Code |
| 2026 | PerfGuard: A Performance-Aware Agent for Visual Content Generation | ICLR | Paper · Code |
| 2026 | CRL-VLA: Continual Vision-Language-Action Learning | arXiv | Paper · Code |
| 2026 | SymbOmni: Evolving Agentic Omni Models via Symbolic Concept Learning | arXiv | Paper · Code |
| 2026 | UI-Mem: Self-Evolving Experience Memory for Online Reinforcement Learning in Mobile GUI Agents | arXiv | Paper · Code |
| 2026 | A Comprehensive Survey of the LLM-Based Agent: The Contextual Cognition Perspective | Preprints | Paper · Code |
3. The Three-Stage Self-Evolving Loop85 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2017 | Proximal Policy Optimization Algorithms | arXiv | Paper · Code |
| 2017 | iCaRL: Incremental Classifier and Representation Learning | CVPR | Paper · Code |
| 2018 | Learning without Forgetting | TPAMI | Paper · Code |
| 2018 | Categorizing Variants of Goodhart's Law | arXiv | Paper · Code |
| 2019 | Efficient Lifelong Learning with A-GEM | ICLR | Paper · Code |
| 2020 | Dark Experience for General Continual Learning: A Strong, Simple Baseline | NeurIPS | Paper · Code |
| 2022 | CodeRL: Mastering Code Generation through Pretrained Models and Deep Reinforcement Learning | NeurIPS | Paper · Code |
| 2023 | Universal Self-Consistency for Large Language Model Generation | arXiv | Paper · Code |
| 2023 | Guiding Pretraining in Reinforcement Learning with Large Language Models | ICML | Paper · Code |
| 2023 | RLTF: Reinforcement Learning from Unit Test Feedback | TMLR | Paper · Code |
| 2023 | Direct Preference Optimization: Your Language Model Is Secretly a Reward Model | NeurIPS | Paper · Code |
| 2023 | Generative Agents: Interactive Simulacra of Human Behavior | UIST | Paper · Code |
| 2023 | Large Language Models Are Human-Level Prompt Engineers | ICLR | Paper · Code |
| 2023 | Scaling Laws for Reward Model Overoptimization | ICML | Paper · Code |
| 2024 | Active Prompting with Chain-of-Thought for Large Language Models | ACL | Paper · Code |
| 2024 | GenSim: Generating Robotic Simulation Tasks via Large Language Models | ICLR | Paper · Code |
| 2024 | Class-Conditional Self-Reward Mechanism for Improved Text-to-Image Models | arXiv | Paper · Code |
| 2024 | Math-Shepherd: Verify and Reinforce LLMs Step-by-Step without Human Annotations | ACL | Paper · Code |
| 2024 | Feedback Loops with Language Models Drive In-Context Reward Hacking | ICML | Paper · Code |
| 2024 | Step-DPO: Step-Wise Preference Optimization for Long-Chain Reasoning of LLMs | arXiv | Paper · Code |
| 2024 | VideoAgent: Self-Improving Video Generation for Embodied Planning | arXiv | Paper · Code |
| 2024 | Autonomous Improvement of Instruction Following Skills via Foundation Models | CoRL | Paper · Code |
| 2024 | Large Language Models as Tool Makers | ICLR | Paper · Code |
| 2024 | Large Language Models as Optimizers | ICLR | Paper · Code |
| 2024 | DSPy: Compiling Declarative Language Model Calls into State-of-the-Art Pipelines | ICLR | Paper · Code |
| 2024 | Loss of Plasticity in Deep Continual Learning | Nature | Paper · Code |
| 2024 | AI Models Collapse when Trained on Recursively Generated Data | Nature | Paper · Code |
| 2024 | Is Model Collapse Inevitable? Breaking the Curse of Recursion by Accumulating Real and Synthetic Data | arXiv | Paper · Code |
| 2025 | UI-TARS-2 Technical Report: Advancing GUI Agent with Multi-Turn Reinforcement Learning | arXiv | Paper · Code |
| 2025 | UniRL: Self-Improving Unified Multimodal Models via Supervised and Reinforcement Learning | arXiv | Paper · Code |
| 2025 | IRIS: Intrinsic Reward Image Synthesis | arXiv | Paper · Code |
| 2025 | MobileGUI-RL: Advancing Mobile GUI Agent through Reinforcement Learning in Online Environment | arXiv | Paper · Code |
| 2025 | DeepSeek-R1 Incentivizes Reasoning in LLMs through Reinforcement Learning | Nature | Paper · Code |
| 2025 | UI-Genie: A Self-Improving Approach for Iteratively Boosting MLLM-Based Mobile GUI Agents | NeurIPS | Paper · Code |
| 2025 | RM-RL: Role-Model Reinforcement Learning for Precise Robot Manipulation | arXiv | Paper · Code |
| 2025 | SRUM: Fine-Grained Self-Rewarding for Unified Multimodal Models | arXiv | Paper · Code |
| 2025 | Diving into Self-Evolving Training for Multimodal Reasoning | ICML | Paper · Code |
| 2025 | Process Reinforcement through Implicit Rewards | arXiv | Paper · Code |
| 2025 | EVOLVE-VLA: Test-Time Training from Environment Feedback for Vision-Language-Action Models | arXiv | Paper · Code |
| 2025 | SmartSnap: Proactive Evidence Seeking for Self-Verifying Agents | arXiv | Paper · Code |
| 2025 | Mobile-Agent-E: Self-Evolving Mobile Assistant for Complex Tasks | arXiv | Paper · Code |
| 2025 | WebCoach: Self-Evolving Web Agents with Cross-Session Memory Guidance | arXiv | Paper · Code |
| 2025 | WebAgent-R1: Training Web Agents via End-to-End Multi-Turn Reinforcement Learning | EMNLP | Paper · Code |
| 2025 | Flow-GRPO: Training Flow Matching Models via Online RL | NeurIPS | Paper · Code |
| 2025 | Real-Time Motion-Controllable Autoregressive Video Diffusion | arXiv | Paper · Code |
| 2025 | Identity-GRPO: Optimizing Multi-Human Identity-Preserving Video Generation via Reinforcement Learning | arXiv | Paper · Code |
| 2025 | OpenWebVoyager: Building Multimodal Web Agents via Iterative Real-World Exploration, Feedback and Optimization | ACL | Paper · Code |
| 2025 | SkillWeaver: Web Agents can Self-Improve by Discovering and Honing Skills | arXiv | Paper · Code |
| 2025 | Self-Improvement in Language Models: The Sharpening Mechanism | ICLR | Paper · Code |
| 2025 | Does Reinforcement Learning Really Incentivize Reasoning Capacity in LLMs Beyond the Base Model? | NeurIPS | Paper · Code |
| 2025 | SyncLoop: A Multimodal Dual-Loop Framework for Self-Improving Mathematical Reasoning | arXiv | Paper · Code |
| 2026 | RISE: Reliable Improvement in Self-Evolving Vision-Language Models | arXiv | Paper · Code |
| 2026 | EvoVid: Temporal-Centric Self-Evolution for Video Large Language Models | arXiv | Paper · Code |
| 2026 | Self-Play Only Evolves When Self-Synthetic Pipeline Ensures Learnable Information Gain | arXiv | Paper · Code |
| 2026 | Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models | ICLR | Paper · Code |
| 2026 | GUI-Genesis: Automated Synthesis of Efficient Environments with Verifiable Rewards for GUI Agent Post-Training | arXiv | Paper · Code |
| 2026 | WebGym: Scaling Training Environments for Visual Web Agents with Realistic Tasks | arXiv | Paper · Code |
| 2026 | Affordance-Graphed Task Worlds: Self-Evolving Task Generation for Scalable Embodied Learning | arXiv | Paper · Code |
| 2026 | Benchmarking LLM Judges for Mobile Agent Evaluation | arXiv | Paper · Code |
| 2026 | Vision-Language Judges Prevent Reward Hacking in Robot Manipulation RL | NeurIPS Workshop | Paper · Code |
| 2026 | MagicGUI-RMS: A Multi-Agent Reward Model System for Self-Evolving GUI Agents via Automated Feedback Reflux | arXiv | Paper · Code |
| 2026 | Self-Correcting VLA: Online Action Refinement via Sparse World Imagination | arXiv | Paper · Code |
| 2026 | Self-Evolving Code-with-Image Reasoning | arXiv | Paper · Code |
| 2026 | Large Reward Models: Generalizable Online Robot Reward Generation with Vision-Language Models | arXiv | Paper · Code |
| 2026 | SARM2: Multi-Task Stage Aware Reward Modeling for Self Improving Robotic Manipulation | arXiv | Paper · Code |
| 2026 | Video-Zero: Self-Evolution Video Understanding | NeurIPS | Paper · Code |
| 2026 | Simple Recipe Works: Vision-Language-Action Models Are Natural Continual Learners with Reinforcement Learning | arXiv | Paper · Code |
| 2026 | From Interaction Traces to Persistent Skills: Online Evolution for Computer-Use Agents | arXiv | Paper · Code |
| 2026 | SIDiffAgent: Self-Improving Diffusion Agent | arXiv | Paper · Code |
| 2026 | EmbodiedRSI: Active Continual Robot Learning through Hypothesis-Guided Co-Evolution | arXiv | Paper · Code |
| 2026 | DenseGRPO: From Sparse to Dense Reward for Flow Matching Model Alignment | arXiv | Paper · Code |
| 2026 | iReasoner: Trajectory-Aware Intrinsic Reasoning Supervision for Self-Evolving Large Multimodal Models | ACL Findings | Paper · Code |
| 2026 | TTRV: Test-Time Reinforcement Learning for Vision Language Models | CVPR | Paper · Code |
| 2026 | M2: Dual-Memory Augmentation for Long-Horizon Web Agents via Trajectory Summarization and Insight Retrieval | arXiv | Paper · Code |
| 2026 | Mem-W: Latent Memory-Native GUI Agents | arXiv | Paper · Code |
| 2026 | UI-Voyager: A Self-Evolving GUI Agent Learning via Failed Experience | arXiv | Paper · Code |
| 2026 | PhysMem: Scaling Test-Time Memory for Embodied Physical Reasoning | arXiv | Paper · Code |
| 2026 | Zetta: An Efficient Closed-Loop Embodied Harness for Self-Evolving Physical Intelligence | arXiv | Paper · Code |
| 2026 | Self-Evolving Embodied Agents via Skill-Harness Evolution | arXiv | Paper · Code |
| 2026 | Recursive Self-Improvement in Unified Multimodal Models | arXiv | Paper · Code |
| 2026 | Wan-R1: Verifiable-Reinforcement Learning for Video Reasoning | arXiv | Paper · Code |
| 2026 | MultiCrafter: High-Fidelity Multi-Subject Generation via Disentangled Attention and Identity-Aware Preference Alignment | CVPR | Paper · Code |
| 2026 | Spurious Rewards: Rethinking Training Signals in RLVR | ICML | Paper · Code |
| 2026 | OpAgent: Operator Agent for Web Navigation | arXiv | Paper · Code |
| 2026 | Tempo-Zero: Recursive Self-Play in Executable Worlds for Video Reasoning | arXiv | Paper · Code |
4. Self-Evolution in Multimodal Reasoning35 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2022 | ChartQA: A Benchmark for Question Answering About Charts with Visual and Logical Reasoning | ACL Findings | Paper · Code |
| 2024 | MathVista: Evaluating Mathematical Reasoning of Foundation Models in Visual Contexts | ICLR | Paper · Code |
| 2024 | MathVerse: Does Your Multi-Modal LLM Truly See the Diagrams in Visual Math Problems? | ECCV | Paper · Code |
| 2025 | Sherlock: Self-Correcting Reasoning in Vision-Language Models | NeurIPS | Paper · Code |
| 2025 | ISR-DPO: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective DPO | AAAI | Paper · Code |
| 2025 | Self-Rewarding Vision-Language Model via Reasoning Decomposition | arXiv | Paper · Code |
| 2025 | Can Large Reasoning Models Self-Train? | arXiv | Paper · Code |
| 2026 | TTRSD: Test-Time Reinforcement Learning with Self-Distillation for Vision-Language Models | arXiv | Paper · Code |
| 2026 | Self-Evolving Vision-Language Models for Image Quality Assessment via Voting and Ranking | ICLR | Paper · Code |
| 2026 | When Models Judge Themselves: Unsupervised Self-Evolution for Multimodal Reasoning | arXiv | Paper · Code |
| 2026 | BUS: Brain-Inspired Unsupervised Self-Reflection via Backward Prediction for Multimodal Reasoning | arXiv | Paper · Code |
| 2026 | Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning | ICML | Paper · Code |
| 2026 | Transductive Visual Programming: Evolving Tool Libraries from Experience for Spatial Reasoning | ICLR | Paper · Code |
| 2026 | Vision-Zero: Scalable VLM Self-Improvement via Strategic Gamified Self-Play | ICLR | Paper · Code |
| 2026 | Spatial Memory Agent: Experience-Grounded Procedure Memory for Spatial Intelligence | arXiv | Paper · Code |
| 2026 | EvoSpatial: Experience-Driven Skill and Tool Evolution for Spatial Reasoning Agents | arXiv | Paper · Code |
| 2026 | M2Note: Continual Evolution of Vision Language Models via Mistake Notebook Learning | arXiv | Paper · Code |
| 2026 | VisualEvolve: A Skill Self-Evolution Framework for Visual Reasoning | arXiv | Paper · Code |
| 2026 | CoWorld Reasoner: Agentic Multimodal Reasoning with the Evolving Video World Model-Driven Harness | arXiv | Paper · Code |
| 2026 | Dynamo: Dynamic Skill-Tool Evolution for Vision-Language Agents | arXiv | Paper · Code |
| 2026 | PhysNote: Self-Knowledge Notes for Evolvable Physical Reasoning in Vision-Language Model | ICLR Workshop | Paper · Code |
| 2026 | Self-Evolving Neuro-Symbolic Skills for Tool-Augmented Spatial Reasoning | arXiv | Paper · Code |
| 2026 | MetaForge: A Self-Evolving Multimodal Agent that Retrieves, Adapts, and Forges Tools On Demand | arXiv | Paper · Code |
| 2026 | Paying More Attention to Visual Tokens in Self-Evolving Large Multimodal Models | arXiv | Paper · Code |
| 2026 | Self-Evolving Visual Questioner | arXiv | Paper · Code |
| 2026 | Trinity: Self-Evolving Vision-Language Models with a Self-Verifier | arXiv | Paper · Code |
| 2026 | Self-Evolving Visual Agent via Margin Reward | arXiv | Paper · Code |
| 2026 | VideoEvoHarness: Self Evolving Agent Harness from Unlabeled Videos for Video Understanding | arXiv | Paper · Code |
| 2026 | EVE: Verifiable Self-Evolution of MLLMs via Executable Visual Transformations | arXiv | Paper · Code |
| 2026 | SpatialEvo: Self-Evolving Spatial Intelligence via Deterministic Geometric Environments | arXiv | Paper · Code |
| 2026 | DUEL: Adversarial Self-Play for Multimodal Reasoning | arXiv | Paper · Code |
| 2026 | Self-Evolving Spatial Reasoning in Vision Language Models via Geometric Logic Consistency | arXiv | Paper · Code |
| 2026 | VICO: Visual Environments Co-Evolving for Vision-Language Model Reasoning | NeurIPS | Paper · Code |
| 2026 | PhysEvolve: Verifier-Grounded Self-Evolution for Physical Reasoning with Executable Worlds | arXiv | Paper · Code |
| 2026 | R-Zero: Self-Evolving Reasoning LLM from Zero Data | ICLR | Paper · Code |
5. Self-Evolution in Multimodal Generation23 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2024 | SceneCraft: An LLM Agent for Synthesizing 3D Scenes as Blender Code | ICML | Paper · Code |
| 2025 | Self-Rewarding Large Vision-Language Models for Optimizing Prompts in Text-to-Image Generation | ACL Findings | Paper · Code |
| 2025 | DanceGRPO: Unleashing GRPO on Visual Generation | arXiv | Paper · Code |
| 2026 | The Image as Its Own Reward: Reinforcement Learning with Adversarial Reward for Image Generation | CVPR | Paper · Code |
| 2026 | PRISM: Prompt Refinement via Image-Grounded Self-Rewarding Mechanism for Text-to-Image Generation | arXiv | Paper · Code |
| 2026 | Safe Autoregressive Image Generation with Iterative Self-Improving Codebooks | ICML | Paper · Code |
| 2026 | Dual-IPO: Dual-Iterative Preference Optimization for Text-to-Video Generation | ICLR | Paper · Code |
| 2026 | Agentic Physics-Grounded Video Generation via Memory-Augmented In-Context Reasoning | arXiv | Paper · Code |
| 2026 | On-Policy Self-Distillation for Multi-Turn Image Editing | arXiv | Paper · Code |
| 2026 | JarvisEvo: Towards a Self-Evolving Photo Editing Agent with Synergistic Editor-Evaluator Optimization | CVPR | Paper · Code |
| 2026 | EvoDesign: Agentic Editable Diagram Creation via Design Expertise Evolution | arXiv | Paper · Code |
| 2026 | Automatic Method Illustration Generation for AI Scientific Papers via Drawing Middleware Creation, Evolution, and Orchestration | arXiv | Paper · Code |
| 2026 | ManimAgent: Self-Evolving Multimodal Agents for Visual Education | arXiv | Paper · Code |
| 2026 | Read It Back: Pretrained MLLMs Are Zero-Shot Reward Models for Text-to-Image Generation | NeurIPS | Paper · Code |
| 2026 | OctoT2I: A Self-Evolving Agentic Text-to-Image Router | CVPR | Paper · Code |
| 2026 | Mutually Adversarial Self-Training with Evolving Data for Unified Multimodal Models | arXiv | Paper · Code |
| 2026 | RSIgen: Reciprocal Self-Improvement for Agentic Visual Generation | arXiv | Paper · Code |
| 2026 | Learning to Generate via Understanding: Understanding-Driven Intrinsic Rewarding for Unified Multimodal Models | arXiv | Paper · Code |
| 2026 | ImageRSI: Verification-Driven Recursive Self-Improvement for Agentic Image Generation | arXiv | Paper · Code |
| 2026 | UniEvo-VL: An On-policy Self-Distillation Training Recipe for Multimodal Model Self-improvement | arXiv | Paper · Code |
| 2026 | COMFYCLAW: Self-Evolving Skill Harnesses for Image Generation Workflows | arXiv | Paper · Code |
| 2026 | MemoGen: Can Past Experience Improve Future Text-to-Image Generation? | arXiv | Paper · Code |
| 2026 | GenEvolve: Self-Evolving Image Generation Agents via Tool-Orchestrated Visual Experience Distillation | arXiv | Paper · Code |
6. Self-Evolution in GUI and Web Navigation19 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2025 | Mobile-Agent-v3: Foundamental Agents for GUI Automation | arXiv | Paper · Code |
| 2025 | ARPO: End-to-End Policy Optimization for GUI Agents with Experience Replay | arXiv | Paper · Code |
| 2025 | Auto-Scaling Continuous Memory for GUI Agent | arXiv | Paper · Code |
| 2025 | Agent S: An Open Agentic Framework that Uses Computers Like a Human | ICLR | Paper · Code |
| 2025 | MobileSteward: Integrating Multiple App-Oriented Agents with Self-Evolution to Automate Cross-App Instructions | KDD | Paper · Code |
| 2025 | AppAgentX: Evolving GUI Agents as Proficient Smartphone Users | arXiv | Paper · Code |
| 2025 | AgentRewardBench: Evaluating Automatic Evaluations of Web Agent Trajectories | COLM | Paper · Code |
| 2026 | ComputerRL: Scaling End-to-End Online Reinforcement Learning for Computer Use Agents | ICLR | Paper · Code |
| 2026 | CRAFT-GUI: Curriculum-Reinforced Agent for GUI Tasks | ICLR Workshop | Paper · Code |
| 2026 | WM-R1: Training GUI Agents to Reason and Leverage World Models with Reinforcement Learning | arXiv | Paper · Code |
| 2026 | What Memory Do GUI Agents Really Need? From Passive Records to Active Task-Driving States | arXiv | Paper · Code |
| 2026 | MobileForge: Annotation-Free Adaptation for Mobile GUI Agents with Hierarchical Feedback-Guided Policy Optimization | arXiv | Paper · Code |
| 2026 | STAMP: Training Explicit Memory for Mobile GUI Agents in Controllable and Scalable Virtual Environments | arXiv | Paper · Code |
| 2026 | SCAFFOLD: Self-Improving Web Agents via Recursive Parametric Skill Abstraction | arXiv | Paper · Code |
| 2026 | Reflect, Revise, Reuse: Training-Free Skill Evolution for GUI Agents | arXiv | Paper · Code |
| 2026 | MAGNET: Towards Adaptive GUI Agents with Memory-Driven Knowledge Evolution | arXiv | Paper · Code |
| 2026 | Agent S4: Evolutionary Computer Use | OpenReview, ICLR 2027 submission | Paper · Code |
| 2026 | Learning to Adapt: Self-Improving Web Agent via Cognitive-Aware Exploration | CVPR | Paper · Code |
| 2026 | GUI-HARVEST: Self-Improving GUI Agents through Evidence-Driven Harness Evolution | arXiv | Paper · Code |
7. Self-Evolution in Embodied Manipulation25 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2021 | Isaac Gym: High Performance GPU-Based Physics Simulation for Robot Learning | arXiv | Paper · Code |
| 2025 | Interactive Post-Training for Vision-Language-Action Models | arXiv | Paper · Code |
| 2025 | _RL: Online RL Fine-Tuning for Flow-Based Vision-Language-Action Models | arXiv | Paper · Code |
| 2025 | A Pragmatist Robot: Learning to Plan Tasks by Experiencing the Real World | arXiv | Paper · Code |
| 2025 | Reflection-Based Task Adaptation for Self-Improving VLA | arXiv | Paper · Code |
| 2026 | RoboBridge: A Self-Evolving Embodied Agent Framework for Sim-to-Real Transfer | arXiv | Paper · Code |
| 2026 | EmbodiedEvo: Self-Evolving Coding Agent for Physical Intelligence | arXiv | Paper · Code |
| 2026 | RoboHarn-Evo: Evolving Hierarchical Physical Knowledge for Self-Improving Robotic Manipulation | arXiv | Paper · Code |
| 2026 | Don't Drop the BATON: Long-Horizon Robot Manipulation via Agentic Subtask Exploration and Transition-Aware Memory | arXiv | Paper · Code |
| 2026 | Harness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents | arXiv | Paper · Code |
| 2026 | ASPIRE: Agentic Skills Discovery for Robotics | arXiv | Paper · Code |
| 2026 | ViSkill: Reinforcing VLM Agents with Evolving Visual-Native Skills | arXiv | Paper · Code |
| 2026 | Policy-Level Recursive Self-Improvement for Embodied AI with a Criticality World Model | arXiv | Paper · Code |
| 2026 | Scale and Selection: What Makes Automatic Harness Evolution Work for Visual-Interface Robot Agents | arXiv | Paper · Code |
| 2026 | RoboEvolve: Co-Evolving Planner-Simulator for Robotic Manipulation with Limited Data | arXiv | Paper · Code |
| 2026 | Motus2: A Self-Evolving General World Model for Dexterous Manipulation | arXiv | Paper · Code |
| 2026 | Evolvable Embodied Agent for Robotic Manipulation via Long Short-Term Reflection and Optimization | arXiv | Paper · Code |
| 2026 | Playful Agentic Robot Learning | arXiv | Paper · Code |
| 2026 | RoboRSI: Stable, Efficient, and Reusable Robot Self-Evolution in Complex Real-World Environments | arXiv | Paper · Code |
| 2026 | Co-Evolving Robot Orchestrators and Policies through Deployment | arXiv | Paper · Code |
| 2026 | WoVR: World Models as Reliable Simulators for Post-Training VLA Policies with RL | arXiv | Paper · Code |
| 2026 | Reinforcing VLAs in Task-Agnostic World Models | arXiv | Paper · Code |
| 2026 | Reconstruct, Practice, Go Real: Guided Self-Improvement for Embodied Agents | arXiv | Paper · Code |
| 2026 | Skills in Weights, Memory in Code: Hybrid Learning for Memory-Dependent Robot Manipulation | arXiv | Paper · Code |
| 2026 | ENPIRE: Agentic Robot Policy Self-Improvement in the Real World | arXiv | Paper · Code |
8. Cross-Scenario Asymmetry14 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 1991 | Dyna, an Integrated Architecture for Learning, Planning, and Reacting | SIGART Bull. | Paper · Code |
| 2018 | Scalable Deep Reinforcement Learning for Vision-Based Robotic Manipulation | CoRL | Paper · Code |
| 2019 | When to Trust Your Model: Model-Based Policy Optimization | NeurIPS | Paper · Code |
| 2024 | OnlineVPO: Align Video Diffusion Model with Online Video-Centric Preference Optimization | arXiv | Paper · Code |
| 2025 | SPRO: Improving Image Generation via Self-Play | NeurIPS | Paper · Code |
| 2025 | SuperFlow: Training Flow Matching Models with RL on the Fly | arXiv | Paper · Code |
| 2025 | Vision-Language Models Can Self-Improve Reasoning via Reflection | NAACL | Paper · Code |
| 2025 | Mind the Gap: Examining the Self-Improvement Capabilities of Large Language Models | ICLR | Paper · Code |
| 2026 | Leveraging Verifier-Based Reinforcement Learning in Image Editing | arXiv | Paper · Code |
| 2026 | SVR-R1: Bootstrapping Multi-Modal Reasoning with Self-Verification in Reinforcement Learning | arXiv | Paper · Code |
| 2026 | Self-Questioning Vision-Language Models: Reinforcement Learning for Compositional Visual Reasoning | arXiv | Paper · Code |
| 2026 | VeriEvol: Scaling Multimodal Mathematical Reasoning via Verifiable Evol-Instruct | arXiv | Paper · Code |
| 2026 | FailBench: How Reliable Are VLMs at Judging Robot Task Success? | arXiv | Paper · Code |
| 2026 | DynaWeb: Model-Based Reinforcement Learning of Web Agents | arXiv | Paper · Code |
9. Self-Evolving Multimodal Agent Evaluation90 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2021 | Inter-GPS: Interpretable Geometry Problem Solving with Formal Language and Symbolic Reasoning | arXiv | Paper · Code |
| 2022 | VIMA: General Robot Manipulation with Multimodal Prompts | arXiv | Paper · Code |
| 2023 | MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI | arXiv | Paper · Code |
| 2023 | HallusionBench: An Advanced Diagnostic Suite for Entangled Language Hallucination and Visual Illusion in Large Vision-Language Models | arXiv | Paper · Code |
| 2023 | GenEval: An Object-Focused Framework for Evaluating Text-to-Image Alignment | arXiv | Paper · Code |
| 2023 | T2I-CompBench++: An Enhanced and Comprehensive Benchmark for Compositional Text-to-image Generation | arXiv | Paper · Code |
| 2023 | VBench: Comprehensive Benchmark Suite for Video Generative Models | arXiv | Paper · Code |
| 2023 | Android in the Wild: A Large-Scale Dataset for Android Device Control | arXiv | Paper · Code |
| 2023 | WebArena: A Realistic Web Environment for Building Autonomous Agents | arXiv | Paper · Code |
| 2023 | LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning | NeurIPS D&B | Paper · Code |
| 2024 | Measuring Multimodal Mathematical Reasoning with MATH-Vision Dataset | arXiv | Paper · Code |
| 2024 | Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall Spaces | arXiv | Paper · Code |
| 2024 | ELLA: Equip Diffusion Models with LLM for Enhanced Semantic Alignment | arXiv | Paper · Code |
| 2024 | OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments | arXiv | Paper · Code |
| 2024 | AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents | arXiv | Paper · Code |
| 2024 | AndroidLab: Training and Systematic Benchmarking of Android Autonomous Agents | arXiv | Paper · Code |
| 2024 | On the Effects of Data Scale on UI Control Agents | arXiv | Paper · Code |
| 2024 | WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models | arXiv | Paper · Code |
| 2024 | VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks | arXiv | Paper · Code |
| 2024 | ManiSkill3: GPU Parallelized Robotics Simulation and Rendering for Generalizable Embodied AI | arXiv | Paper · Code |
| 2024 | RoboCasa: Large-Scale Simulation of Everyday Tasks for Generalist Robots | arXiv | Paper · Code |
| 2024 | VLABench: A Large-Scale Benchmark for Language-Conditioned Robotics Manipulation with Long-Horizon Reasoning Tasks | arXiv | Paper · Code |
| 2024 | BEHAVIOR-1K: A Human-Centered, Embodied AI Benchmark with 1,000 Everyday Activities and Realistic Simulation | arXiv | Paper · Code |
| 2024 | Are We on the Right Way for Evaluating Large Vision-Language Models? | arXiv | Paper · Code |
| 2024 | Confronting Reward Overoptimization for Diffusion Models: A Perspective of Inductive and Primacy Biases | ICML | Paper · Code |
| 2024 | MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark | ICML | Paper · Code |
| 2025 | PhysBench: Benchmarking and Enhancing Vision-Language Models for Physical World Understanding | arXiv | Paper · Code |
| 2025 | MMSI-Bench: A Benchmark for Multi-Image Spatial Intelligence | arXiv | Paper · Code |
| 2025 | MMVU: Measuring Expert-Level Multi-Discipline Video Understanding | arXiv | Paper · Code |
| 2025 | WISE: A World Knowledge-Informed Semantic Evaluation for Text-to-Image Generation | arXiv | Paper · Code |
| 2025 | ScienceBoard: Evaluating Multimodal Autonomous Agents in Realistic Scientific Workflows | arXiv | Paper · Code |
| 2025 | LIBERO-PRO: Towards Robust and Fair Evaluation of Vision-Language-Action Models Beyond Memorization | arXiv | Paper · Code |
| 2025 | RoboTwin 2.0: A Scalable Data Generator and Benchmark with Strong Domain Randomization for Robust Bimanual Robotic Manipulation | arXiv | Paper · Code |
| 2025 | DISCOVERSE: Efficient Robot Simulation in Complex High-Fidelity Environments | arXiv | Paper · Code |
| 2025 | GenEval 2: Addressing Benchmark Drift in Text-to-Image Evaluation | arXiv | Paper · Code |
| 2025 | Evo-Memory: Benchmarking LLM Agent Test-Time Learning with Self-Evolving Memory | arXiv | Paper · Code |
| 2025 | LifelongAgentBench: Evaluating LLM Agents as Lifelong Learners | arXiv | Paper · Code |
| 2025 | Building Self-Evolving Agents via Experience-Driven Lifelong Learning: A Framework and Benchmark | arXiv | Paper · Code |
| 2025 | VL-RewardBench: A Challenging Benchmark for Vision-Language Generative Reward Models | CVPR | Paper · Code |
| 2025 | Multimodal RewardBench: Holistic Evaluation of Reward Models for Vision Language Models | arXiv | Paper · Code |
| 2025 | MJ-Bench: Is Your Multimodal Reward Model Really a Good Judge for Text-to-Image Generation? | NeurIPS D&B | Paper · Code |
| 2025 | WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning | ICLR | Paper · Code |
| 2025 | VisualPRM: An Effective Process Reward Model for Multimodal Reasoning | arXiv | Paper · Code |
| 2025 | Self-Improving VLM Judges without Human Annotations | arXiv | Paper · Code |
| 2026 | RoboLab: A High-Fidelity Simulation Benchmark for Analysis of Task Generalist Policies | arXiv | Paper · Code |
| 2026 | RoboDojo: A Unified Sim-and-Real Benchmark for Comprehensive Evaluation of Generalist Robot Manipulation Policies | arXiv | Paper · Code |
| 2026 | Do Androids Dream of Breaking the Game? Systematically Auditing AI Agent Benchmarks with BenchJack | arXiv | Paper · Code |
| 2026 | EvoMemBench: Benchmarking Agent Memory from a Self-Evolving Perspective | NeurIPS | Paper · Code |
| 2026 | Benchmarking Continual Agent Memory for Online Learning, Transfer, and Forgetting | ICLR Workshop | Paper · Code |
| 2026 | AgentCL: Toward Rigorous Evaluation of Continual Learning in Language Agents | arXiv | Paper · Code |
| 2026 | PATH-Bench: Path-Dependent Evaluation of Lifelong Agents | arXiv | Paper · Code |
| 2026 | Are Self-Evolving Agents Continual Learners? | arXiv | Paper · Code |
| 2026 | EvoHarnessBench: Can Your Agents Keep Pace with an Evolving Harness? | arXiv | Paper · Code |
| 2026 | Evo-Bench: Can Language Models Improve Agent Harness? | arXiv | Paper · Code |
| 2026 | Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents | arXiv | Paper · Code |
| 2026 | EvoAgentBench: Benchmarking Agent Self-Evolution via Ability Transfer | arXiv | Paper · Code |
| 2026 | SEA-Eval: A Benchmark for Evaluating Self-Evolving Agents Beyond Episodic Assessment | arXiv | Paper · Code |
| 2026 | FinEvo-Bench: A Longitudinal Benchmark for Self-Evolving Agents in Professional Financial Workflows | arXiv | Paper · Code |
| 2026 | FinEvolveBench: A Benchmark for Self-Evolving Agents on Low-Repetition Tasks with Implicit Rewards | arXiv | Paper · Code |
| 2026 | GDPevo: Evaluating Agent Self-Evolution on Real Business Tasks | arXiv | Paper · Code |
| 2026 | Beyond Endpoint Performance: Process-Level Evaluation of Self-Evolving Agents | arXiv | Paper · Code |
| 2026 | Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions | ICLR | Paper · Code |
| 2026 | WorldMemArena: Evaluating Multimodal Agent Memory through Action–World Interaction | NeurIPS | Paper · Code |
| 2026 | LongMemEval-V2: Evaluating Long-Term Agent Memory Toward Experienced Colleagues | arXiv | Paper · Code |
| 2026 | CGL: Advancing Continual GUI Learning via Reinforcement Fine-Tuning | arXiv | Paper · Code |
| 2026 | Continual GUI Agents | arXiv | Paper · Code |
| 2026 | Agentic-MME: What Agentic Capability Really Brings to Multimodal Intelligence? | arXiv | Paper · Code |
| 2026 | MemGUI-Bench: Benchmarking Memory of Mobile GUI Agents in Dynamic Environments | arXiv | Paper · Code |
| 2026 | MMG2Skill: Can Agents Distill In-the-Wild Guides into Self-Evolving Skills? | arXiv | Paper · Code |
| 2026 | GameBoyWorlds: A Testbed for Self-Improvement in Embodied Video Games | arXiv | Paper · Code |
| 2026 | Where is Physical RSI Capability From? An Observational Scaling Law of LLM-as-Policy | arXiv | Paper · Code |
| 2026 | Learning the Task or Learning the Verifier? Rethinking Criteria Exposure in Embodied Self-Improvement | arXiv | Paper · Code |
| 2026 | Flex-RSI: Benchmarking Recursive Self-Improvement of Frontier Agents | arXiv | Paper · Code |
| 2026 | Video Understanding Reward Modeling: A Robust Benchmark and Performant Reward Models | arXiv | Paper · Code |
| 2026 | AndroidFlux: Evaluating and Reward Modeling Failure Recovery Capabilities in Mobile Use Multimodal Agents | arXiv | Paper · Code |
| 2026 | Don't Read the Log: Execution Traces Contaminate Verifiers in Video-Generation Agents | arXiv | Paper · Code |
| 2026 | Multimodal Reward Hacking in Reinforcement Learning | arXiv | Paper · Code |
| 2026 | IsoVRBench: Video Reward Modeling Without Human Feedback | arXiv | Paper · Code |
| 2026 | Understanding Reward Hacking in Text-to-Image Reinforcement Learning | arXiv | Paper · Code |
| 2026 | RobotAgentBench: Towards Open-World Robot Autonomy | arXiv | Paper · Code |
| 2026 | Mastering PokeGym: Graph-Guided Multimodal Evolution at Test Time | arXiv | Paper · Code |
| 2026 | GameVerse: Can Vision-Language Models Learn from Video-Based Reflection? | arXiv | Paper · Code |
| 2026 | OmniGameArena: A Unified UE5 Benchmark for VLM Game Agents with Improvement Dynamics | arXiv | Paper · Code |
| 2026 | SelfImprove-Bench: Evaluating Generalization in Self-Improving Agents | arXiv | Paper · Code |
| 2026 | EmbodiedCLBench: Evaluating Continual Learning for Self-Evolving Embodied Agents | arXiv | Paper · Code |
| 2026 | MC-EvoBench: Auditing Experience-Driven Self-Improvement in Minecraft Agents | arXiv | Paper · Code |
| 2026 | Self-Verifier Capture in Unified Visual Generators: Diagnosing and Repairing Closed-Loop Self-Reward | arXiv | Paper · Code |
| 2026 | More Convincing, Not More Correct: Self-Play Reward Hacking of Reference-Free LLM Judges | arXiv | Paper · Code |
| 2026 | SOLE-R1: Video-Language Reasoning as the Sole Reward for On-Robot Reinforcement Learning | arXiv | Paper · Code |
| 2026 | Who Sets the Pace of Judge Hacking? Judge Capability versus the Policy–Judge Gap | arXiv | Paper · Code |
10. Open Challenges4 papers
| Year | Title | Venue | Links |
|---|---|---|---|
| 2026 | EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience | arXiv | Paper · Code |
| 2026 | Your Agent May Misevolve: Emergent Risks in Self-evolving LLM Agents | ICLR | Paper · Code |
| 2026 | On Safety Risks in Experience-Driven Self-Evolving Agents | ACL Findings | Paper · Code |
| 2026 | Learning from Runtime Feedback through Failure-Bank Self-Evolution for Vision-Language-Action Models | arXiv | Paper · Code |
Citation
If you find this survey useful, please cite it as follows.
@article{jiang2026selfevolvingmmagents,
	title   = {A Cross-Scenario Survey and Analysis of Self-Evolving Multimodal Agents},
	author  = {Jiang, Jingjing},
	journal = {arXiv preprint arXiv:2611.14256},
	year    = {2026}
}